AI-Powered Reviewer Recommendations: How PeerSubmit Simplifies Academic Peer Review
Paige Watson
Published on 07 November 2026Effective AI reviewer recommendation software should do more than match a few repeated keywords. It should understand research topics and abstract content, evaluate expertise relevance, explain every recommendation, guard against invalid results, and keep the program chair in control. That is the standard behind PeerSubmit's RAG-powered reviewer matching pipeline.
Choosing a reviewer is one of the most consequential decisions in peer review. A weak match can produce a superficial evaluation. A strong match brings the subject knowledge and methodological understanding needed to assess a paper fairly. PeerSubmit helps conference chairs identify stronger candidates without surrendering the final assignment decision to automation.
How PeerSubmit's AI Reviewer Recommendation Software Supports Better Matching
PeerSubmit combines retrieval-augmented generation (RAG), semantic vector similarity, keyword overlap, structured reviewer profiles, conflict indicators, and constrained LLM reranking. Each layer solves a different part of the matching problem.
- Understands meaning: embeddings compare the semantic content of a paper with reviewer expertise, not only exact phrases.
- Uses the full academic context: title, abstract, keywords, track, form answers, manuscript details, AI-generated summaries and insights can contribute to the match.
- Retrieves before it generates: the LLM evaluates a focused set of real reviewers instead of inventing names.
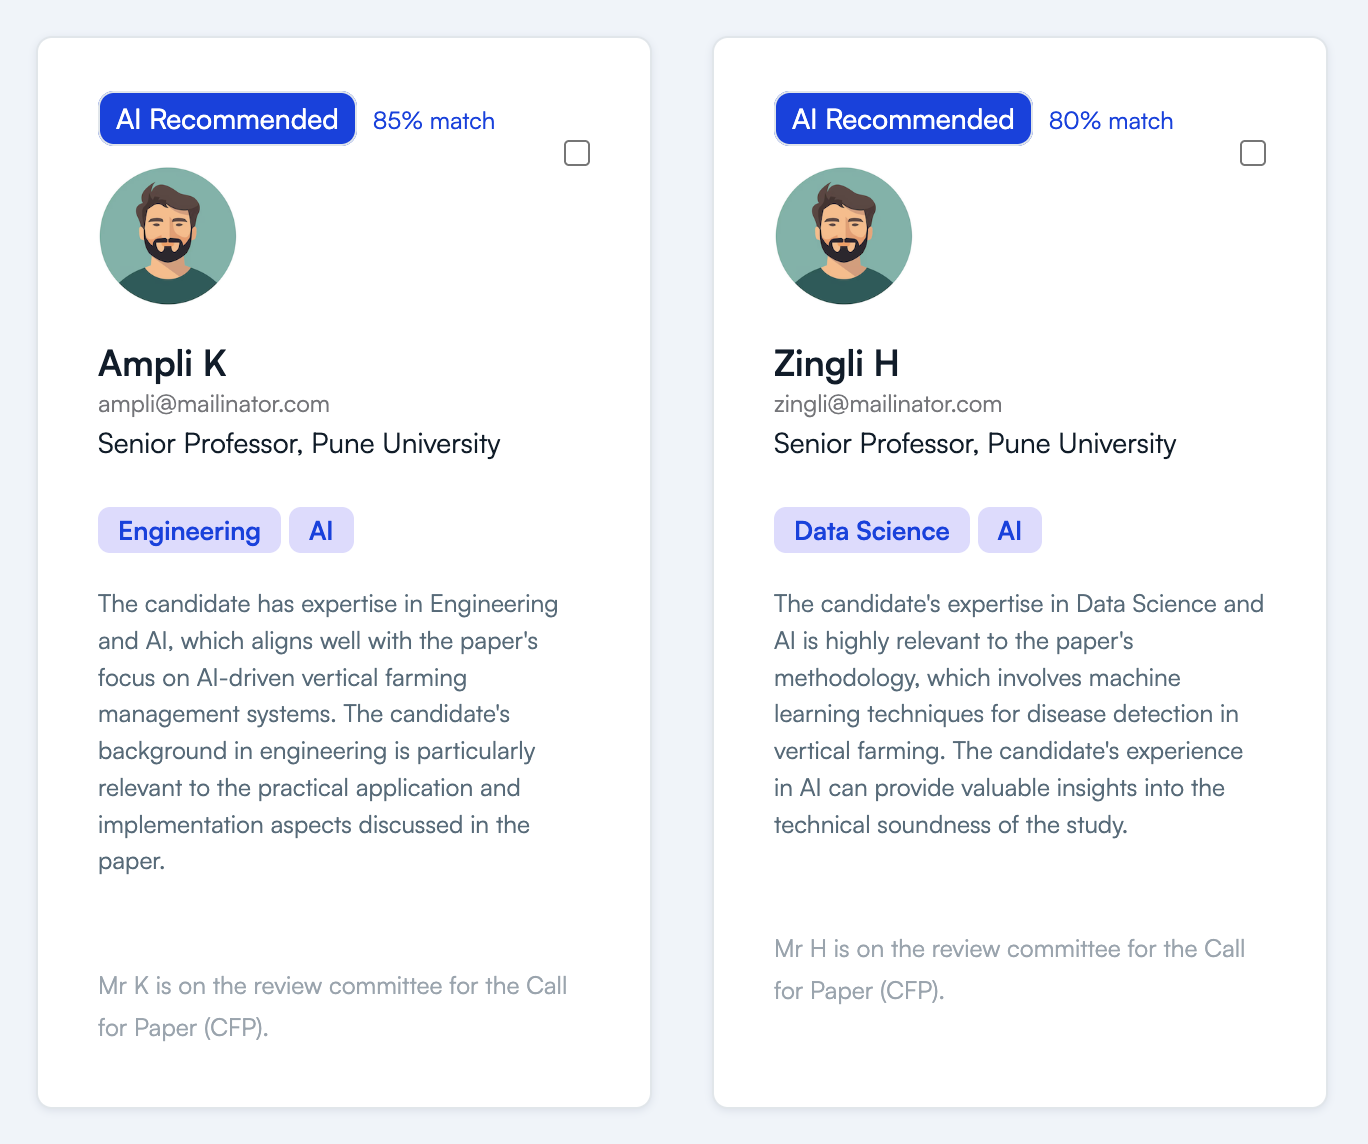
- Explains the recommendation: chairs see a match score, matching expertise, and a plain-language reason.
- Preserves human oversight: AI recommends; the organizer reviews conflicts, workload, availability, and makes the assignment.
What Is RAG in Reviewer Recommendation?
RAG stands for retrieval-augmented generation. Instead of asking a language model to choose from an undefined universe of people, PeerSubmit first retrieves the strongest candidates from the conference's own reviewer committee. The LLM then reranks only those supplied candidates using the paper's academic context.
This separation matters. Vector retrieval is efficient at finding semantically related profiles. The LLM is useful for interpreting why expertise, methodology, track relevance, and affiliations matter together. Combining both produces a more controlled recommendation than either layer alone.
PeerSubmit Reviewer Recommendation RAG Pipeline

Pipeline summary: Paper context → embeddings → semantic retrieval → constrained LLM reranking → explainable recommendations → human decision.
How PeerSubmit Identifies Relevant Reviewers
1. It builds a richer representation of the paper
The recommendation process can use the submission title, abstract, author keywords, selected track, track description, structured submission responses, manuscript details, extracted manuscript text, AI summary, review insights, verdict insights, and author affiliations. This gives the system more evidence than a title-only or keyword-only matcher.
2. It represents reviewer expertise semantically
Reviewer expertise, designation, and organization are transformed into embeddings. Embeddings place related ideas closer together even when authors and reviewers use different terminology. For example, a paper may mention “plant disease detection,” while a reviewer profile lists “computer vision” and “machine learning.” Semantic retrieval can recognize the relationship.
3. It combines vector and lexical evidence
PeerSubmit's retrieval score currently gives 80% weight to semantic vector similarity and 20% to lexical overlap. Vector similarity captures meaning; lexical overlap preserves strong explicit signals such as a specialized method or named research field. The strongest candidates move into the reranking stage.
4. It asks the LLM to rerank real candidates only
Up to 20 retrieved candidates are sent to the recommendation model. The model is instructed to rank only the supplied candidate IDs and to assess subject expertise, methodology, track relevance, and likely affiliation conflicts. It returns up to five recommendations with a 0–100 match score, a reason, and the expertise that supports the match.
5. It validates the model output
PeerSubmit rejects candidate IDs that were not present in the retrieved reviewer set, removes duplicates, clamps scores to the valid range, and limits the result count. If the LLM is temporarily unavailable, the semantic retrieval ranking provides a deterministic fallback instead of leaving the organizer with no guidance.
6. It explains rather than silently assigns
The recommendation card shows why a reviewer may fit the submission. The program chair can compare that reasoning with the reviewer's expertise and then consider workload, availability, seniority, institutional policy, and conflicts before checking the assignment box.
How Many Tokens Does Each Recommendation Use?
Token use depends on paper length, the number and depth of reviewer profiles, and whether embeddings are already cached. The following ranges describe the current typical engineering estimate—not a guaranteed fixed allowance.
| Recommendation stage | First request | Repeated request |
|---|---|---|
| Paper embedding | Up to approximately 2,000 tokens | Cached |
| Reviewer embeddings | Approximately 50–150 tokens per reviewer | Cached when the profile is unchanged |
| LLM recommendation input | Approximately 2,500–7,000 tokens | Approximately 2,500–7,000 tokens |
| LLM recommendation output | Approximately 200–500 tokens | Approximately 200–500 tokens |
Typical first recommendation with 20 reviewers: approximately 5,000–12,000 total embedding and LLM tokens.
Typical repeat recommendation after embedding cache: approximately 2,700–7,500 LLM tokens.
Embeddings are cached for 30 days using a content-based key. If the underlying paper or reviewer profile changes, PeerSubmit generates a fresh vector for the changed content. Actual usage can be lower or higher than these ranges.
Designed to Reduce Hallucination and Protect Reviewer Choice
Reviewer recommendation is a high-context decision, so unrestricted generation is the wrong pattern. PeerSubmit constrains the recommendation model to reviewers already attached to the event. It sends the reviewer ID and professional matching context needed for ranking—not an open-ended request to name experts from the internet.
- The LLM may select only supplied candidate IDs.
- Unknown or duplicated candidate IDs are discarded.
- The system returns supporting reasoning rather than a hidden score alone.
- Organizers remain responsible for final conflicts, workload, and assignment approval.
Why This Is Better Than Keyword-Only Matching
Keyword systems are useful but brittle. They can miss synonyms, related methodologies, interdisciplinary connections, and contextual meaning. Pure LLM matching has the opposite problem: it may be expensive, difficult to constrain, and vulnerable to unsupported suggestions. PeerSubmit's hybrid RAG architecture uses each technology where it is strongest.
- Embeddings: discover semantic relationships.
- Lexical overlap: retain direct terminology matches.
- RAG retrieval: narrow the decision to real conference reviewers.
- LLM reranking: interpret subject, method, track, and affiliation evidence together.
- Human oversight: account for policy and circumstances the model cannot know.
Technology That Supports Academic Judgment
No reviewer-matching system can guarantee the right expert for every paper. PeerSubmit instead identifies evidence-based candidates from the conference's available reviewer pool, presents the reasoning behind each match, and leaves approval with the chair. The architecture is designed for relevance, constraint, resilience, transparency, and practical conference workflows—not as a replacement for academic judgment.
That combination is why PeerSubmit is a strong choice for universities, scholarly societies, journals, and conference committees seeking a modern AI reviewer recommendation system. It helps chairs reach a better shortlist faster while preserving the human responsibility at the heart of peer review.
Start Running Your Conference—From Submission to Decision
Join hundreds of organizers who trust PeerSubmit to manage their academic events with AI-powered efficiency and seamless workflows.
No credit card required • Setup in minutes
AI Reviewer Recommendation Software FAQs
Run Your Conference Without the Chaos
Manage submissions, peer review, registrations, and event workflows—all in one platform built for academic conferences.
Join hundreds of academic conferences already using PeerSubmitNo credit card required • Setup in minutes